Earlier this week Tristan published his top YouTube channels:
thume.ca/2026/11/01/you…
Which looked excellent so clearly I had to turn it into TristanTube:
karpathy.ai/tristan-tube/
47K super nerdy videos +TV mode for laid back watching. (One-shotted with Claude Code in 3 minutes)
Weekend hack: HackerTube. I was annoyed with YouTube's recommendations so I had Claude filter down 43M comments over 20 years of HN to 6,454 videos that keep being recommended. *Significantly* better viewing experience, ~2 hours with Opus 5.5:
hackertube.org
- Excellent recs without any logins (state is kept in local browser session)
- Thumbnail is a representative frame from middle of the video instead of the super duper A/B test hyper-optimized user uploads
- Underlying data from the comment analysis as one zip file, point your Claude at it and ask for your own version
- HackerTube Longs ✊
A bit more on the process:
I use Claude Code (desktop app for Mac), Opus 5.5 on Medium effort as my default. I only talk to Claude and have it do everything, the only "manual work" I helped with in tandem was in the browser (reminiscent of MenuGen): 1) I had to create some kind of API key from Google Cloud UI to query YouTube for video metadata, 2) I booted up a VPS box for serving and 3) I bought the domain name. Once the box was up I gave Claude the IP and told it update, secure, harden, deploy and optimize the code, and it did the whole thing.
Many awesome projects that would have normally taken weeks/months even can now be few-shotted for breakfast. What else are we not thinking of.
Introducing Arete-27B: Qwen3.8-27B, post-trained to reinforce Western values.
Chinese open models are currently the strongest available, but they ship with state-aligned behavior in the weights. We built an 803-prompt eval across seven value categories, including freedom of expression, democracy, and privacy, and measured how often a model adopts China’s party line.
After fine-tuning on roughly 53 million tokens, Arete-27B's propaganda rate fell from 22% to 1%, in line with the Western models we tested. Its Hermes Bench score shows no significant performance tradeoffs.
The values in an open model are one fine-tune away.
Our eval, weights, and training data are available now along with the full blog post: nousresearch.com/arete
Across our projects @GoogleDeepMind, we are witnessing a genuine phase transition in the pace of scientific discovery. You will see a glimpse of this in our releases in the next few weeks.
I admit that I completely broke down today. I cried uncontrollably. I couldn’t hold myself together after witnessing what I saw with my own eyes.
Today, we went to film a journalistic report inside the displacement tents along the seashore. I swear, what we witnessed was beyond what any human being should have to endure.
I saw men crying bitterly. Men I had never seen cry when they lost their children or when their homes were destroyed. Today, I saw them crying because they were powerless to do the simplest thing: protect their children from the water and the cold.
We spoke to families who told us they had spent the entire night carrying their children in their arms after floodwater covered the floors of their tents and soaked their mattresses. They couldn’t find a single dry place to put their children. They couldn’t even give them a few hours of sleep.
I saw children no older than five, without proper clothes to protect them from the cold, without heating, and without a dry place to sleep. Children shivering inside tents that cannot keep out the rain, protect them from the wind, or provide even the most basic sense of safety.
What more must happen for this world to act? How much more suffering must people endure before someone remembers that they are human beings?
I am sick of this world. I am sick of its hypocrisy and empty slogans. To hell with a world that talks endlessly about human rights while leaving children to drown inside their tents. To hell with everyone who has witnessed this suffering and chosen silence, and to hell with the governments and institutions that have the power to act but continue to turn their backs on us.
Omarchy is forever free. There's no monetization scheme coming. I'm already rich and the Omacom Foundation is a well-founded nonprofit.
The only ulterior motive here is to make Linux win on the desktop and create the perfect, malleable computer for all to enjoy!
Merhaba Istanbul!
What a stunning view from the Grand Bazaar this morning alongside talented creator Cem Başak. Thrilled to visit this remarkable country!
American ambition. Maximum power.
We didn’t reach for the stars to stop pushing farther. Under @POTUS’ leadership, we’re going back to the Moon. This time, to stay. 🇺🇸
President Trump at @NASA's Kennedy Space Center. 🚀
"To be an American is to inherit the legacy of the greatest pioneers, explorers, inventors, and innovators... Now, our nation is ready to prove the doubters wrong yet again — and to make the next giant leaps for all mankind."
Happy Diwali to everyone celebrating around the world! May the light of this festival brighten your year ahead. Shot on iPhone 18 Pro Max by Gursimran Basra.
Two things I’ve been thinking about regarding AI:
• People often highlight the risks involved in AI, which are surely very real. I’m struck, however, by how hard it is to understand the contours of the positive scenario. There are easy-to-perceive and frequently invoked elements of a positive vision — more diseases cured, more material abundance, etc. — which sound great, but these are by themselves just ingredients. I’m curious what the larger equilibrium is supposed to look like. Do people work? If so, why? What is their marginal contribution? If not, how are resources allocated? What is scarce? What is the ratio between humans and AIs? Are humans in control, whatever that means? One sometimes hears the Culture novels invoked as one scenario, but I’m not sure they depict a desirable outcome. (AI runs everything and humans compete in games? Iain Banks himself said that the humans in the Culture are “somewhere between passengers, pets and parasites.”) There is Richard Brautigan’s famous poem, but do we want to be “returned to our mammal brothers and sisters”? (Isn’t that rewinding Genesis?) We could say that it was hard to imagine the world of 1900 from the vantage point of 1700, and that’s assuredly true. But nobody in 1700 was trying to recast humanity itself within a couple of years — things necessarily unfolded slowly and by increments, and therefore with the possibility for error correction. Given how rapid the rate of progress in AI may be, it feels strange for the upside case to be so opaque.
• There is increasing discussion of whether AIs are conscious or how we would know whether they are, with conclusions there often assumed to be relevant to matters of moral worth. At first blush, this seems a rather arcane, benign, or even absurd issue. (Remember the response to Blake Lemoine’s fears.) Setting aside the terms of the debate itself, or the relevant demarcation criteria, it seems to me a quite high-stakes question, for an affirmative answer — that is, granting moral worth to AIs — would presumably mean that the aggregate worth of AIs would soon outweigh that of humans in any utilitarian calculus. The AIs will be exceptionally wise and intelligent, and vastly more numerous (especially once one considers the imminent future and the AIs not yet born). As such, even epsilon of moral worth will multiply to a lot once one considers the quadrillions that could soon exist. (This is effectively a distributed version of the Nozick’s utility monster.) If this conclusion is unpalatable, I think one of three propositions needs to be rejected: the premise AIs can have moral worth; utilitarianism itself; or the belief that there is even a possibility that they will be far more numerous than humans.
With both of these matters (contours of future society; AI moral worth), there is the possibility of dramatic change. Today, people argue about datacenters. I’m curious how popular support for AI will evolve as more people come to understand these medium-term questions and the relevant stakes. What is the vision for AI that most people would be excited about?
Check out Google's Elephant-Goldfish Model, our new open-source plugin → goo.gle/480yn2n
Draft specs with deep-context agents and stress-test them with zero-context subagents before writing code. You make the architectural decisions and approve the spec before implementation. Works with Antigravity, Claude, Codex and ChatGPT.
I was shocked that 3/4s of designers work in coding agents rather than design tools. This is crazy?? Designers deserve a tool built for them, not just for developers.
That's why I'm building @proto_ide, the designer’s IDE. The shape of Claude Code and Cursor, but with every design feature you wish they’d ship.
Early access signups are open. If you want a tool that finally unlocks your full creative potential, sign up at prototypes.fun :)
Disengaging from syntax is not disengaging from engineering.
I’m working on a significant project at the moment. It’s in a pre-production state so far. More than a prototype, less than ready for real users.
I’ve been making multiple passes over the structure for each of the following concerns: Architecture, coverage, race & concurrency, security, API, etc. Each of these requires significant interrogation and review of verification procedures; but not review of the code.
At base are the /ub-mode (GitHub.com/unclebob) rules that keep the agents disciplined as far as coding structure and tests are concerned. But above that it’s me making sure that all the bases are covered well enough to keep my client safe from stupid sloppy mistakes.
I am the engineer. I am responsible. The agents are just my tools. They are power tools, to be sure. But power tools in the hands of novices result in missing fingers. So I am very careful.
Introducing Theseus Robotics (YC F26).
Our robots restocks supermarket shelves overnight and picks online orders by day, without changing anything in the store.
Lights off at 9pm, shelves full by 9am. Next stop: San Francisco.
Today we're announcing Atomarine's $19M seed round!
We are supported by great investors including @ycombinator, @PanteraCapital, @Soma_Capital , @sevensevensix, @Liquid2V, @AudaciousHQ, @e14fund, and many others.
@Atomarine_co is solving the main constraint to AI today: physical buildout. Our floating data centers powered by nuclear, are designed to be built on a single production line, and anchored offshore.
By moving offshore, we do not compete with communities for water, power or land, and we do not drive up their electricity bills or rent. This allows America to stay competitive in the AI race without putting the burden on local communities, while fighting climate change by scaling AI on nuclear instead of fossil fuels.
We have already built a functional proof of concept and we are now racing towards our next big milestone.
If you are a very talented engineer in naval architecture, nuclear or data center design, or just love to work at world-changing, fast-paced companies, reach out. We are hiring!
if you’re working for a company in cybersecurity, you should be evaluating your options to abstract your companies services from the internet
what i mean is: why allow an unauthenticated anonymous agent of an attacker to interact with your systems?
consider your architectural levers now, you’re going to need them
Altman, Hassabis, and Amodei are the ones doing massive corporate lobbying at the moment.
They are the ones who are attempting to perform a regulatory capture of the AI industry.
You, Geoff, and Yoshua are giving ammunition to those who are lobbying for a ban on open AI R&D.
If your fear-mongering campaigns succeed, they will *inevitably* result in what you and I would identify as a catastrophe: a small number of companies will control AI.
The vast majority of our academic colleagues are massively in favor of open AI R&D. Very few believe in the doomsday scenarios you have promoted.
You, Yoshua, Geoff, and Stuart are the singular-but-vocal exceptions.
like many, I very much support open AI platforms because I believe in a combination of forces: people's creativity, democracy, market forces, and product regulations.
I also know that producing AI systems that are safe and under our control is possible. I've made concrete proposals to that effect.
This will all drive people to do the Right Thing.
You write as if AI is just happening, as if it were some natural phenomenon beyond our control.
But it's not. It's making progress because of individual people that you and I know. We, and they, have agency in building the Right Things.
Asking for regulation of R&D (as opposed to product deployment) implicitly assumes that these people and the organization they work for are incompetent, reckless, self-destructive, or evil. They are not.
I have made lots of arguments that the doomsday scenarios you are so afraid of are preposterous. I'm not going to repeat them here. But the main point is that if powerful AI systems are driven by objectives (which include guardrails) they will be safe and controllable because *e* set those guardrails and objectives.
(Current Auto-Regressive LLMs are not driven by objectives, so let's not extrapolate from their current weaknesses).
Now about open source: your campaign is going to have the exact opposite effect of what you seek.
In a future where AI systems are poised to constitute the repository of all human knowledge and culture, we *need* the platforms to be open source and freely available so that everyone can contribute to them.
Openness is the only way to make AI platforms reflect the entirety of human knowledge and culture.
This requires that contributions to those platforms be crowd-sourced, a bit like Wikipedia.
That won't work unless the platforms are open.
The alternative, which will *inevitably* happen if open source AI is regulated out of existence, is that a small number of companies from the West Coast of the US and China will control AI platform and hence control people's entire digital diet.
What does that mean for democracy?
What does that mean for cultural diversity?
*THIS* is what keeps me up at night.
Crazy days when comparably-priced laptops, like the XPS and Omnibook, can beat MacBook Neo at the battery game so decisively. I would not have guessed the $700 laptop category would have gotten such competitive, awesome PC options this quickly. youtube.com/watch?v=Obb8u6…
It looks like the AI layoff boom has started to backfire.
I was just going through a Reuters investigation on Meta, and holy shit...
They drew up plans to cut some teams by as much as 60% and let AI agents do the work. THEN Zuckerberg called off the next round of layoffs hours before the first one even started.
And when you look at the numbers... they tell you why.
Engineers were pushing out 220% more code, BUT major technical and security incidents jumped 40%.
So people spent 70% more time putting out fires.
AI cranked out way more work, and humans spent way more time cleaning it up.
A different report I saw this week showed something similar.
32% of hiring managers said they brought back the exact jobs they cut for AI.
Think about how dumb that is. You fire people, pay a fortune for AI, then pay again to hire the same people back.
Look, I’m no AI bear. I use AI every single day.
It saves me a shit ton of time and I’m not going back. It’s an incredible tool.
But market forces are still market forces.
Every boom in history has been overhyped, and every CEO wanted to stand up and tell Wall Street he could do more with half the people.
Now from what I’m seeing, reality is kicking in.
It costs way more than they thought, it breaks shit, and you still need people who know what the hell they’re doing.
Even the AI companies are feeling it. Elon just cut Grok’s usage limits and admitted it costs more to run than it brings in.
I still think AI is a great bet, and I’m still buying the companies building the data centers. But you need balance, and the guys who went all in on firing everyone are learning that the hard way.
Be careful out there.
In office hours with a startup, I suggested they focus on selling to their batchmates, because it would be both the real test of whether their product was good and also the best influence on its evolution. They went to work, and they just crossed 10% of the batch using it.
Finally solved the long-standing issue with Linux on Apple Silicon, power management
Neo during suspend now draws **0.05 W** on average, just like macOS. It cuts off the power rail to SoC while keeping DRAM in self-refresh loop and still supports wake over LAN/USB/BT, so it works well in docked setups too
And now it's finally possible to just let your Mac running Linux sleep for days without losing battery (well, negligible amounts)! Most of the time was spent covering all sorts of edge cases with USB / weird coprocessor gotchas across suspend
As expected, it wasn't too big like the GPU work was (just difficult to get right, and touches a fairly big amount of subsystems to implement suspend/wake in each) - needed me to sit down for a while and actually get it done... it took a lot of tiny details to get here, but I've finally developed a nearly complete understanding of how it works. 2 days into this rabbit hole and the result is, deep sleep works on Neo and expectedly super similar across M4-M6, where deep WFI looks a little different, others on team like Andreas and @tiredkebab have gotten it to work on M1/M2 as well
Technical deep dive in a blog post coming soon from me and @RyanTheTide regarding the whole Neo bringup we did in the matter of 2 months, it's been a lot of fun & it's just the beginning of what @AuroraSilicon team is doing with @OmarchyMac
Will be working on shipping this feature to our mainline kernel now
Do you want to be an astronaut?
Applications are now open to join NASA's astronaut corps. Join us as we expand the frontiers of discovery in low Earth orbit, on the Moon, and beyond — apply by Dec. 3: go.nasa.gov/4iGqLqu
20 years ago there was a building in SF that was nicknamed the Y Scraper because so many YC founders lived there. They just had a reunion and it makes me so happy to see them all. One thing you can say for sure about YC: no investor's founders become closer friends.
I'm grateful for the work Asahi did on Apple Silicon, and in the best open source spirit, we've been expanding that with TouchID, M3 GPU, DisplayPort over USB-C, deep sleep, MacBook Neo. But thanks to agent acceleration, Asahi rejects upstreaming 🤷
The Asahi project was all about taking something closed and restricted and opening it up.
Adding new restrictions that make it harder for other projects to build on that is not the way. And that AI rejection is just silly.
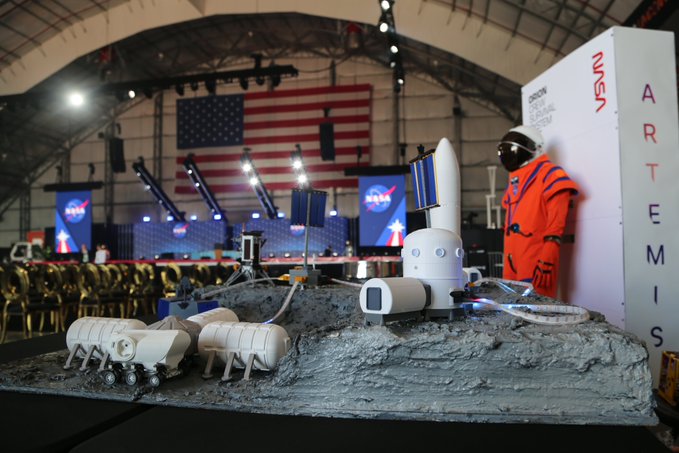
New awards. New mission updates. More progress toward a Moon Base.
We're advancing commercial lunar deliveries, a nuclear-powered rover, launch and orbital transfer services, and infrastructure to support a sustained human presence on the Moon:
A lot of people think Boom is dividing our efforts equally between supersonic and energy—or that we've abandoned supersonic entirely and are only doing energy.
Neither of those is correct. Here's what we're really doing.
Boom is very deliberately doing energy first, then supersonic. We'll get the engine working on the ground, generating gigawatts and gigadollars. Then we'll take everything we've learned (and some of the cash) and build the supersonic airliner.
Right now, we have ~165 people, of which ~5 are on the airplane.
This might mean that Overture will be a year or two later than we hoped—but also the probability that it actually happens is much, much greater than ever before. United's CEO gave us 50/50 odds, which I see as a strong endorsement. Never before in history has there been *any* effort with a 50% chance of producing a practical supersonic airliner!
By the time Superpower ships to customers next year, I think the odds will be well over 50%.
And for me personally, I'm just 100% committed to both energy and flight. I'm here for the day when we have to explain to kids that NYC to SF used to take 6 hours and that supersonic flight wasn't normal.
Just announced at MAX POWER: a $1 million Moon Base Student Challenge! go.nasa.gov/3UBpcCs
The competition tasks U.S. high school and post-secondary student teams to develop solutions to real-world engineering constraints for establishing a long-term human presence on the Moon.
"LLMs engender harms to the pillars of Asahi Linux: software freedom, the open-source community, the open Internet, the environment, digital privacy, user consent, and software developers themselves... we broadly forbid the use of generative AI." 🙄
Omarchy on Apple Silicon has gotten a lot of attention, but our efforts to make all Snapdragon PCs compatible is really taking off too. I personally now also have a @ASUS Zenbook 14 and 16 running with Omarchy in addition to the BlueChip. Please help!
Agents have returned the computer to those glorious early days when the Commodore 64 and Amstrad 464 booted straight into a BASIC prompt: An open invitation to create things!
It's magical how agents are allowing people all over to independently bring up Apple Silicon compatibility with Omarchy. The barriers to entry and collaboration are getting destroyed. Great job, Dylan! 🤘
Omarchy on the M4 MacBook Pro, progress update:
Working: all 10 CPU cores at full clocks, GPU acceleration, native display at 120Hz + 10-bit, all 3 USB-C ports at 10Gb/s, Wi-Fi, Bluetooth, all 6 speakers, hardware video decode
Next up: HDR, VRR, mics, camera, Thunderbolt
@dhh@omarchy@OmarchyUpdates@OmarchyMac
American ambition at full throttle. 🇺🇸
An incredible first day of MAX POWER at @NASAKennedy with @airdotshow, and we’re not done yet. This is just a taste of what’s ahead with @capeweek_us.
More power. More inspiration. Let’s go!
We're kicking Moon Base updates into high gear! 🚀
Tune in today at 5 p.m. ET as agency leaders share the latest progress and new developments in our efforts to establish a sustained human presence on the lunar surface. The event will stream live from MAX POWER at @NASAKennedy.
Attention, quelles que soient vos opinions politiques par ailleurs, cette mesure de LFI est extrêmement nocive pour la France en terme écologique, géopolitique, et économique.
L’Allemagne a fait pareil et c’est un fiasco, qui lui a coûté très cher.
Elle s’est retrouvé dépendante du gaz russe et du nucléaire français pour continuer son activité, et a même dû rouvrir des centrales à charbon ultra-polluantes.
Et ce malgré un investissement dans les renouvelables de 500 milliards d’euros (que la France n’a clairement pas les moyens de s’offrir !)
Et en terme géopolitique, l’Allemagne se retrouve dépendante du gaz russe et américain.
La France se retrouverait complètement soumise aussi à des pays hostiles comme la Russie, l’Algérie, les USA, etc. sur son énergie.
La question de l’énergie est trop vitale et importante dans un espace mondialisé, là c’est pas juste une question d’opinion politique, c’est la survie du pays qui est en jeu : ne votez surtout pas LFI.
Jean-Luc Mélenchon balaie le programme EPR2 : la France insoumise veut sortir des énergies fossiles avant 2050 mais aussi du nucléaire pour passer au 100% renouvelables
l.bfmtv.com/s8Le
Maybe both parties keep mistaking voter rejection of their opponents’ agenda for an endorsement of their own sweeping platform, when voters really just want a president who fixes the proverbial potholes.
Good morning from MAX POWER @NASAKennedy!✈️
The tech toys are on display, aircraft are fueled up, and NASA experts are ready to meet you!
Follow along on @NASA_Events for updates and more views from our aerospace expo and air show.
Can't stop thinking how much stuff Jev is doing to save AI engineers asses from stupid systems design patterns while the rest of the domain keeps pushing tool calling loops everywhere
Why don't we at TypeSafe call Jev a decision model?
If you think of Jev's questions as making *decisions*, I believe you'll use it at the wrong layer of abstraction and your reliability will suffer.
I wrote all about this on our site 🧵👇
There's one great example that shows how physics can help upgrade AI world models, and it's LeHami.
@ylecun, @randall_balestr and @RominaYalov brought Hamiltonian mechanics into JEPA to preserve phase-space volume and prevent latent collapse during long-term predictions.
Why exactly Hamiltonian mechanics?
• Variables are coordinates q and momenta p (not velocities like in Lagrangian mechanics), giving LeHami paired first-order equations for updating its states.
• This makes Hamiltonian H a central function. It's often total energy: kinetic + potential, in classical mechanics.
• LeHami learns this H function with kinetic-like K(p) and potential-like V(q, u) components, where u represents actions.
• A symplectic leapfrog integrator uses this function to predict how states evolve depending on the actions taken, while no constrains are violated.
To understand this better it's useful to think of a pendulum. It can pass the same position in either direction. But physical position alone won’t predict what comes next, you also need momentum.
LeHami follows a similar principle, but works with learned representations of position and momentum.
→ And most importantly, it builds a constraint into how those predictions evolve.
Maybe that's exactly the kind of thing world models like JEPA need now - one less way to go wrong.
We've taken a much deeper look at LeHami's design and results in this guide. Plus, there's a little mechanics lesson for AI and physical AI folks that's worth learning → turingpost.com/p/lehami-expla…
Such an awesome, empirically rigorous benchmark!! 🙌
Holding the model fixed and still seeing a ~2x swing in solve rate -- and ~11.7x difference in cost per solved task -- is proof of how much the harness actually matters. (And Harness Lens documenting prompts, tools, and compaction across 34 harnesses is 😍.)
Would love to see this exact methodology run on frontier proprietary models across open harnesses next! 👀
I burned a shitload of compute so you don't have to. Releasing the Harness Leaderboard.
Which harness should you run your open model in? I ran 28,849 trials to find out.
The leaderboard compares nine coding-agent harnesses on open models. In each comparison only the harness changes: the model, provider and reasoning effort stay fixed, and every task gets three attempts.
The trials ran GLM-5.3-Flash, DeepSeek-V4.1-Flash and Flint on Terminal-Bench 2.1 and DeepSWE, for $4,746 of inference.
Averaged over the three models, mini-swe-agent (@KLieret), a bash-only agent, solves 51.4% of tasks and @openclaw 27.3%. Four others are statistically tied with mini-swe-agent.
One of them is Pi (@pidotdev), at 49.4% for $0.29 per solved task, about 45% less than mini-swe-agent's $0.53.
The best harness depends on the model: mini-swe-agent on GLM-5.3-Flash, Hermes Agent (@NousResearch) on DeepSeek-V4.1-Flash and Kimi Code (@Kimi_Moonshot) on Flint.
@opencode costs $3.35 per solved task, 11.7 times as much as Pi.
See Harness Hub's Harness Lens for what the nine harnesses do differently. It documents the prompts, tools and compaction of 34 coding-agent harnesses and links every claim to its source.
Leaderboard: huggingface.co/spaces/joelnik…
Harness Lens: huggingface.co/spaces/harness…
The P in JEPA stands for predictive.
The main distinction is not between JEA and JEPA, but between Joint Embedding (predictive or not) and generative architectures.
Whether a predictor is necessary depends on the task.
Given observations x and y (y being available only during training), a generative architectures predicts y from x. The loss is the divergence between y and its prediction:
L = divergence(y, pred(enc(x)) )
A JEA encodes y as well and minimizes the divergence between the representations of x and y, while preventing collapse:
L = divergence( enc(y), enc(x) ) + R( enc(y), enc(x) )
Where R is the anti-collapse regularizer, which may be computed over a batch of samples.
JEA are used when the prediction has no particular direction, i.e. when x and y are different views of the same scene. The idea for JEA is very old. Becker and Hinton proposed a simple model in 1989 where the anticollapse was based on information maximization. Schmidhuber had a version in 1992 based on redundancy minimization. At NIPS 1993, I proposed Siamese nets, which was a contrastive method to train JEA. Such contrastive methods gained popu.arity after Google's SimCLR paper in 2020. In 2021, Stéphane Deny in my group proposed the Barlow Twins redundancy reduction regularizer, which seemed to work at scale. This was shortly followed by VICReg by Adrien Bardes, Jean Ponce, and me, and last year by SIGReg by Randall Balestriero and me.
DINO is a JEA method that comes from a long string of papers from Piotr Bojanowski's group at FAIR-Paris, starting with Noise as Targets (2017), Deep Clustering (2018-2020), and DINO v1-v3 which are contrastive between clusters, not samples.
JEPA adds a predictor, which is useful when the prediction is non-symetric. For example, when x is a degraded/corrupted version of y, or when x is a present observation and y a future observation (temporal prediction). The loss is:
L = divergence( enc(y), pred(enc(x)) ) + R( enc(y), enc(x) )
All of these models can be augmented by an action variable a, fed to the predictor, encoding an action, intervention, or transformation to produce y from x.
This turns the system into a "world model". In a JEPA, the loss becomes
L = divergence( enc(y), pred(enc(x), a) ) + R( enc(y), enc(x) )
Several comments:
1. image/video SSL methods differ by whether they use reconstruction or not. Joint embedding architectures Amy or may not have a predictor (JEA vs JEPA). They also differ by their anti-collapse method and data corruption/augmentation methods.
2. DINO *is* a kind of JEPA (technically a JEA). The difference with other JEPA models is the anti-collapse criterion (based on contrative clustering+ stopgradient/EMA), and the data augmentation scheme (image transformations, which is task specific),
3. V-JEPA 2.1, like DINO, is from Meta-FAIR (corporate lab), involved significant engineering teams, large/proprietary datasets, considerable computing resources, lots of fine-tuning, and number-pushing on many benchmarks.
4. Many JEPA papers are applications and/or fine-tuned versions of DINO, V-JEPA or I-JEPA.
5. LeJEPA, LeWM, and most other papers with "JEPA" in the title are *research* papers focused on the methodology, often done by students in academic labs, involving no engineering support, very little computing resources, and small/public training sets. They are generally tested on toy problems, simulated environments, or small/public benchmarks.
6. You simply cannot compare 5 with 2/3/4. 5 gives you ideas and new methods, not models. 2/3 give you well-engineered models, with lots of empirically validated tricks. Only rarely will 2/3 give you a new, well-principled method with room to spare. 5 give you empirical results on new applications.
7. What is published in 5 are methods that will eventually become like 2 and 3, whenever someone with resources picks it up and scales it.
DO NOT CONFUSE UPSTREAM FOUNDATIONAL RESEARCH ON METHODS AND DOWNSTREAM SCALING -> ENGINEERING -> NUMBER PUSHING -> MODELS -> PRODUCTS.
The former makes the rest possible, but it takes time.
Replit was building toward the AI coding era years before it had a name. In 2024, the company shipped an agent that could take a request in plain English, work through errors, provision its own infrastructure, and keep going until the software actually worked. The model companies even reached out to ask how Replit had pulled it off.
Co-founder and CEO Amjad Masad had been thinking about making programming radically more accessible since 2008, and Replit’s original pitch deck predicted AI-generated code before the Transformer paper was published. Today, that same technology is moving into banks, manufacturers, and other large companies, where Amjad says teams are replacing software projects once scoped at $10 million with $250,000 of Replit.
On How to Build the Future, @paulg sits down with @amasad to talk about why @Replit was so well positioned when coding agents arrived, what comes after vibe coding, and his bigger vision for the “self-driving company,” where AI agents increasingly build and operate the software a company needs.
00:00 - "You guys basically invented vibe coding"
02:43 - Watching users copy-paste from ChatGPT
05:27 - The origins of Replit
08:00 - People underestimate their ability to predict the future
10:27 - Grieving the craft
12:52 - A culture of obsessing over users
15:13 - Why enterprises pick Replit
17:28 - The agent was just another user
20:17 - It barely worked, and users loved it
23:13 - $10 million projects now for $250,000
25:45 - Sandboxing for humans
28:14 - "The self-driving company"
30:34 - The way AI flows into companies
33:28 - What Steve Jobs knew before the iPad
35:59 - Killing the sacred cow
38:25 - The rest of the world is two years behind
41:15 - The compute brought on AI
43:46 - The person who assumes dramatic change
This week’s Paper Club is all about AI for biology.
Sequencing costs have collapsed, biology is generating more data than researchers can make sense of, and the models are beginning to catch up. The opportunity now is to move from reading biological data to modeling and designing living systems.
We brought together researchers and builders working across cancer genomics, virtual cells, genome language models, and biological design to show what that shift looks like in practice.
We start with a single patient, asking how AI can build a research program around their cancer, then zoom out to whole cells and genomes. Along the way, we look inside a language model trained on DNA and explore how in-context learning emerged even though the model was never explicitly trained to do it.
00:00 - Is the Turing test solved? A live experiment
03:22 - Why now is the best time for AI Bio
08:26 - Alfredo Gonzalez: cancer as a data problem
29:50 - Yusuf Roohani: virtual cells and autonomous research
51:47 - Garyk Brixi: what a model learns from DNA
1:09:57 - Divya Nori: few-shot prompting for biological design
Arthur Mensch vient de poser sur LinkedIn la phrase que les députés devraient lire avant le 19 novembre : quand Mistral choisira entre un data center en Essonne ou hors de France, la loi Darcos pèsera dans la balance.
Donc le Sénat a voté le texte à l'unanimité le 8 avril : dans un litige civil, dès qu'un indice rend vraisemblable l'utilisation d'une œuvre, on présume qu'elle a été utilisée par le fournisseur du modèle, et c'est à lui de prouver le contraire. Les défenseurs du texte ont un vrai argument : aujourd'hui, un auteur n'a ni les données d'entraînement ni les moyens techniques de prouver quoi que ce soit. Mais en face, prouver qu'une œuvre n'a pas servi sur des milliards de mots pose une question que personne ne tranche : quelles preuves le juge exigera, à quel coût, et qu'est-ce qu'il faudra ouvrir de ses secrets d'affaires pour les fournir. Mensch dit que c'est impossible sans livrer ses méthodes.
Et ce qui a changé depuis avril, c'est que les décisions d'investissement se prennent maintenant. Mistral a sorti Large 4, 1 000 milliards de paramètres, poids ouverts, entraîné à Bruyères-le-Châtel sur ses propres machines. L'entreprise développe 1 GW de capacité, essentiellement en Europe et largement en France. Pour l'ordre de grandeur, 1 GW, c'est à peu près la puissance d'un réacteur nucléaire, et on ne choisit pas l'emplacement de ce genre d'infra pour deux ans mais pour dix.
Mon inquiétude, c'est que la loi pèse surtout sur ceux qui entraînent en France. Sur le papier, un acteur étranger qui vend ici peut être attaqué ici. En pratique, une boîte qui a ses serveurs et ses équipes en Essonne est bien plus facile à aller chercher qu'une boîte qui entraîne en Californie.
En avril, j'écrivais déjà que la solution adulte était sur la table : une contribution sur le chiffre d'affaires réalisé en Europe, appliquée à tous, étrangers compris, qui finance la création sans transformer chaque entraînement en contentieux potentiel. Tout reste à construire, de la répartition entre créateurs à l'articulation avec les licences existantes, mais c'est la bonne direction. Mensch la repropose aujourd'hui, adossée à l'article 53 de l'AI Act. Sept mois plus tard, on rejoue le même débat, avec un modèle français de plus entre les deux.
Ma hot take : les créateurs devront s'adapter à l'IA, et les plateformes feront le nécessaire. Spotify vient de signer avec Believe pour des remix IA, avec le consentement des artistes et une rémunération à la clé. Ce n'est pas l'entraînement des modèles, mais ça montre qu'on peut payer les créateurs par des accords plutôt que par des procès.
On a enfin une boîte française capable de jouer dans la cour des grands, qui entraîne ses modèles chez nous et investit dans nos infrastructures. Et c'est maintenant qu'on décide de lui mettre des bâtons dans les roues ? C'est elle qui aura, la première, à arbitrer entre l'Essonne et ailleurs.
L'AI Act oblige déjà les fournisseurs de modèles à publier un résumé de leurs données d'entraînement et à mettre en place une politique de respect du droit d'auteur. Bruxelles travaille maintenant sur les évolutions de ce cadre, notamment la question de l'utilisation et de la rémunération des œuvres protégées. Et pendant ce temps, la France veut ajouter son propre mécanisme de présomption, avec le risque de multiplier les contentieux avant même qu'une réponse européenne commune se dessine. On ne pouvait pas coordonner tout ça à l'échelle européenne ?
À force de vouloir réglementer les champions qu'on n'avait pas, on risque de décourager ceux qu'on a enfin.
La France a parmi les meilleurs mathématiciens et ingénieurs IA du monde. On le sait. On les embauche partout ailleurs. Et la première chose qu'on fait au moment où on pourrait enfin capitaliser dessus ? On vote une loi qui transforme l'entraînement d'un modèle sur sol européen en parcours du combattant juridique.
À l'unanimité. Avec le sourire.
Le 8 avril 2026, le Sénat adopte la proposition de loi Darcos-Evren-Ouzoulias. Nouvel article L. 331-4-1 du Code de la propriété intellectuelle. Mécanisme : présomption d'utilisation des contenus culturels par les systèmes d'IA. Dès qu'un indice (développement, déploiement ou output) rend l'usage d'une œuvre protégée « vraisemblable », c'est à l'entreprise de prouver qu'elle ne l'a pas exploitée. Inversion de la charge de la preuve.
Sur le papier, c'est « David contre Goliath ». Dans les faits, c'est surtout « Goliath américain et chinois qui s'en fout » contre « Mistral et les boîtes européennes qui jouent encore le jeu du sol ».
Soyons clairs : les présomptions existent en droit, c'est un mécanisme connu. En matière de contrefaçon, ça fonctionne. Mais ici, on parle de prouver un négatif sur des datasets de centaines de milliards de tokens. La question n'est pas de savoir si c'est juridiquement possible en théorie. La question, c'est le coût de conformité, l'incertitude massive et le risque juridique concret que ça fait peser sur tout acteur qui entraîne ou déploie en Europe. Rien que ce risque suffit à décourager l'investissement. Et c'est exactement ce qui va se passer.
Maintenant, posons le problème de fond : l'extraterritorialité.
Une boîte américaine ou chinoise peut entraîner son modèle chez elle, sur n'importe quelles données, sans contrainte, puis venir vendre ses services en Europe.
Une boîte française qui veut faire la même chose subit toute la contrainte sur son sol, avec ses données, avec ses capitaux.
Le résultat est prévisible : les acteurs étrangers captent le marché européen sans friction, les acteurs locaux portent seuls le poids de la conformité. C'est exactement le piège de la régulation asymétrique. On crée un avantage compétitif pour ceux qu'on prétend combattre.
OpenAI, Google, Meta ont entraîné leurs modèles frontier massivement sur le web ouvert entre 2022 et 2025. C'est un fait documenté, contesté en justice : le NYT a attaqué OpenAI, Getty a attaqué Stability AI, les procès sont en cours. Ce n'est pas que personne n'a réagi. C'est que la régulation arrive quatre ans après les faits, mal calibrée, et qu'elle ne touche pas ceux qui ont déjà engrangé l'avantage. Les modèles sont entraînés. Les poids sont dans la nature. C'est fini.
Et c'est là que le décalage avec la réalité technique devient vertigineux.
En 2026, sur un PC à 2 000 euros, n'importe qui fait tourner Qwen 3.5, Gemma4, GLM en local. Niveau frontier de 2024/2025 voir 2026. Sans garde-fous, sans journal de bord, sans rien. Les modèles sont open, distillés, parfois « obligatered » : sans aucune restriction.
Demande à Gemini de reproduire une œuvre, il te dira non. Télécharge un modèle open en local, tu fais ce que tu veux. La loi ne touche pas ça. Elle ne touche que ceux qui déclarent leur activité en Europe et qui veulent scaler légalement. On pénalise la transparence.
Ce n'est plus une affaire de « géants de l'IA » contre les créateurs. La démocratisation est totale. Le narratif « Big Tech pille les artistes » était peut-être pertinent en 2022. En 2026, c'est une grille de lecture obsolète qui ignore la réalité du terrain. La vraie mesure utile serait d'imposer aux modèles fermés qui opèrent en Europe des garde-fous anti-copie stricts c'est là que le levier existe, c'est là que l'enforcement est possible. Pas de compliquer l'entraînement pour tout le monde.
Parlons de qui cette loi protège vraiment.
On nous dit « les créateurs ». Les artistes face au pillage. Mais quand on regarde de plus près, les bénéficiaires ne sont pas les créateurs indépendants. Ce sont les sociétés de gestion collective historiques (CNC, SACEM), les lobbys culturels qui défendent un modèle économique du XXe siècle face à une technologie qui compresse le temps de création par un facteur 1000.
Un youtubeur qui conjugue IA et création humaine ? Il n'est pas protégé par cette loi. Il est dans le viseur ou menacé indirectement. Un créateur indépendant qui nourrit son process avec du prompting ? Pareil. La loi protège le statu quo culturel, pas la création de demain.
Le modèle de rémunération des créateurs doit évoluer, c'est une évidence. L'IA compresse en quelques minutes ce qui prenait des mois. Il n'y a pas de bouton pour revenir en arrière. Mais la réponse n'est pas de bloquer la technologie avec des lois qui ne s'appliquent qu'à ceux qui jouent le jeu.
La réponse, c'est de construire un mécanisme de redistribution qui fonctionne dans le monde tel qu'il est, pas tel qu'on voudrait qu'il soit.
Et justement, cette réponse existe. @MistralAI l'a posée sur la table.
Mistral, le seul champion français de l'IA presque frontier. La boîte qui vient de lever 830 millions de dollars pour construire ses data centers près de Paris.
Arthur Mensch, son CEO, a publié le 20 mars dans le Financial Times une tribune proposant une contribution obligatoire de 1 à 5 % du chiffre d'affaires des fournisseurs d'IA opérant en Europe, versée dans un fonds européen destiné à indemniser les créateurs. Transparente. Mesurable. Appliquée à tout le monde y compris les Américains et les Chinois qui vendent ici. C'est de l'équilibre économique réel.
Ça finance la création sans tuer l'entraînement. Ça résout le problème d'extraterritorialité parce que la contribution s'applique au chiffre d'affaires réalisé en Europe, pas au lieu d'entraînement. On a préféré la présomption de culpabilité.
Maintenant, zoomons arrière. Parce que le sujet des auteurs, c'est une toute petite partie de l'iceberg.
L'IA, c'est une révolution. Pas un sujet de commission parlementaire entre deux cafés. C'est la plus grande redistribution de puissance technologique depuis Internet. Pendant qu'on débat de « pillage » et de « chalutage des contenus », la Chine forme des armées de robots autonomes, les États-Unis signent des contrats défense à 20 milliards avec Anduril et Palantir, et les labos chinois distillent les modèles américains pour les retourner contre eux. Nous, on en est encore à se demander si l'IA est « vraiment intelligente ».
Le décalage entre la réalité technique et la compréhension qu'en ont ceux qui légifèrent est abyssal. Et je pèse mes mots. Quiconque a passé un weekend avec un modèle frontier un GPT-5.4 un opus4.6 à 200 dollars par mois sait que ce n'est pas un gadget.
>>> C'est un accélérateur cognitif qui change fondamentalement la manière dont on travaille, dont on crée, dont on raisonne.
-> Voter une loi sur l'IA sans avoir jamais poussé un de ces modèles dans ses retranchements, c'est comme réguler l'automobile en n'ayant jamais conduit.
La France a une carte exceptionnelle. Le talent mathématique. L'énergie nucléaire pour alimenter les data centers. Une volonté de souveraineté qui, parfois, se traduit en actes concrets. Mais à chaque révolution technologique, on fait la même erreur : on protège d'abord les rentes du passé au lieu de construire les champions de demain. Et le résultat est toujours le même : on forme les meilleurs ingénieurs, qui partent chez Google, OpenAI ou Anthropic.
La mondialisation a déjà bouffé nos boîtes malgré une révolution industrielle plutôt réussie. Nos entreprises n'ont pas eu le réflexe d'aller à l'étranger, de mettre en jeu leur IP, de jouer la compétition mondiale. On a préféré rester dans notre petit marché, protégés par nos petites lois. Et quand le train est passé, on a regardé.
Celui-là ne repassera pas.
Quand tu sabotes le process d'entraînement, tu sabotes les marges. Tu sabotes l'innovation. Tu sabotes l'intégration verticale.
C'est le même principe que dans le manufacturing : celui qui contrôle le process contrôle les marges et la souveraineté. Tesla l'a compris avec ses Gigafactories. Apple l'a compris avec ses puces. Et nous, on fait exactement l'inverse. On met des bâtons dans les roues de nos propres constructeurs pendant qu'on continue de signer des chèques à Palantir pour nos besoins en données stratégiques.
On fait fuir les entrepreneurs. On fait fuir les talents. On fait fuir les sachants. Et quand on n'aura plus que les yeux pour pleurer, on continuera d'applaudir les lois votées à l'unanimité en se demandant pourquoi on est à la traîne.
Ce n'est pas David contre Goliath. C'est la France qui se tire une balle dans le pied, toute seule, avec le sourire, à l'unanimité, en se disant qu'elle protège la culture française.
La solution adulte était sur la table : contribution sur le CA, appliquée à tous, garde-fous anti-copie stricts sur les modèles fermés. Pas une présomption qui transforme tout développeur européen en suspect par défaut et qui ne change rien pour le type qui fait tourner un modèle open en local sur son PC.
Contrôle du process ou dépendance éternelle. On est en train de choisir la seconde.
Réveillez-vous.
The @GoogleDeepMind Science team is sharing two key cryptographic advances today uncovering weaknesses in legacy 1024-bit RSA schemes.
Working with leading cryptanalysis experts, our team showed how AI agents could make two significant cryptographic advances in just weeks, uncovering results which can bypass older digital signature protections and factor legacy 1024-bit RSA keys in bulk.
While these results do not affect the security of modern encryption schemes such as RSA 2048, these results show why we must not assume the mathematical "hardness" of cryptographic schemes which we have relied upon in the past. It also shows how AI can help defenders improve security standards well ahead of future threats.
I have written in more detail about our results, and why they are important for the future of security, in a longer essay which you can read here:
How do you move AI customer agents from prototype to production in weeks?
Darshan Kantak shares practical takeaways from 5 enterprise rollouts on unifying voice and chat, winning on real-time reasoning, and empowering your developers to own the AI stack end to end ↓ goo.gle/4sP4WKa
We have a lot of fun talking to founders on The Social Radars, but occasionally they send me into a laughing fit. We had to pause taping after Blake described the "head schmutz" on the ceilings above all window seats so I could pull myself together.
Gemini agents have distinct identities, role-based access controls, and complete audit trails.
Watch the full special episode of Google Cloud Live → goo.gle/4zrkIgK
1 million downloads of SimReady assets on @HuggingFace. 🎉
SimReady assets help teams use 3D content across supported tools and simulation workflows, from robot workcells to AI factory digital twins.
Thank you to everyone experimenting, sharing feedback and building with SimReady assets.
Find assets for your next simulation in SimReady Central: huggingface.co/spaces/nvidia/…
Your agent may have started the work, but you can finish the task in your IDE.
Open a GitHub Copilot app session directly in @code. The task, plan, conversation, and code changes all come too (so you don't need to start over 😅).
Here's every step ⬇️
ICYMI: spend caps on Google Cloud Budgets are generally available.
Updates include:
- Automation through spend caps API
- Real-time visibility with live cost reports
- Automated guardrails for your monthly resets
Learn how the new spend caps can help your business here → goo.gle/4zxg9Br
💡 Bring all your related work together with projects in the GitHub Copilot app.
Give Copilot a goal and it will coordinate the work. Your project can span one or more repos or focus on tasks that don't require one. Copilot can start sessions, set up recurring automations, or create artifacts; they'll show up in your project. 🗂️
Keep your sessions together to work toward one objective. Get started 👇
docs.github.com/copilot/how-to…
I burned a shitload of compute so you don't have to. Releasing the Harness Leaderboard.
Which harness should you run your open model in? I ran 28,849 trials to find out.
The leaderboard compares nine coding-agent harnesses on open models. In each comparison only the harness changes: the model, provider and reasoning effort stay fixed, and every task gets three attempts.
The trials ran GLM-5.3-Flash, DeepSeek-V4.1-Flash and Flint on Terminal-Bench 2.1 and DeepSWE, for $4,746 of inference.
Averaged over the three models, mini-swe-agent (@KLieret), a bash-only agent, solves 51.4% of tasks and @openclaw 27.3%. Four others are statistically tied with mini-swe-agent.
One of them is Pi (@pidotdev), at 49.4% for $0.29 per solved task, about 45% less than mini-swe-agent's $0.53.
The best harness depends on the model: mini-swe-agent on GLM-5.3-Flash, Hermes Agent (@NousResearch) on DeepSeek-V4.1-Flash and Kimi Code (@Kimi_Moonshot) on Flint.
@opencode costs $3.35 per solved task, 11.7 times as much as Pi.
See Harness Hub's Harness Lens for what the nine harnesses do differently. It documents the prompts, tools and compaction of 34 coding-agent harnesses and links every claim to its source.
Leaderboard: huggingface.co/spaces/joelnik…
Harness Lens: huggingface.co/spaces/harness…
“Founded by Ben and Felicia Horowitz, the Paid in Full Foundation honors the hip-hop immortals whose artistic contributions far outweigh the financial remuneration they received in return.”
“As Ben described Eric B. & Rakim’s debut masterpiece, the foundation’s namesake Paid in Full: ‘I bought it for $10 and got at least $5 million worth of value out of it. It needed to be paid back.’”
“Each honoree receives a five-year grant with no strings attached. Inspired by Quincy Jones’ work with the Jazz Foundation, the grants have allowed past recipients, among them Rakim, Scarface, George Clinton, Roxanne Shanté, Grandmaster Caz, Kool Moe Dee, Grand Puba, and Kool G Rap, to purchase homes, pay off medical bills, and finish long-delayed creative projects.”
“Of course, a few grants a year can’t repay an entire generation, but they’re a start. Paid in Full refuses to let these cultural giants languish in our midst, and its grants have fundamentally changed the artists’ lives, though still not as much as the artists changed ours.”
Full piece from acclaimed music journalist Jeff Weiss on the Paid in Full Foundation’s 2026 Hip Hop Grandmaster Awards:
@Passionweiss
TensorFold is awesome! Thanks to @MiaAI_lab and @0xSero for turning me on to this project. It's going to be key to our local AI recipes for out-of-the-box agents on NVIDIA 🤘
TensorFold is coming to Omarchy 🚀
TensorFold recipes are already in Omarchy's local AI catalogue for Qwen3.8-27B, Flash Next and Nemotron 3.5 Bolt.
Seeing that is pretty wild. 🤯
Huge thanks to @dhh and the Omarchy contributors for all the work that went into this.
I want local AI to be easier and faster to use on your own machine, and I'm really excited to contribute to this.
github.com/omacom/omarchy…tensorfold.dev
"One research group wanted to study ten men in the North of England who ate five or more servings of fruit and vegetables a day. They couldn’t find any, though, so had to lower their target to three servings."
stevestewartwilliams.com/p/why-men-die-…
Many people in tech have made, or are about to make, large sums of capital. I want to make a petition for more philanthropy towards historical buildings- specifically Churches
Every year, dozens of historical Churches fall into disrepair around Europe. Hundreds of these deconsecrated buildings are up for sale
I don't believe you need to be Christian to recognise the value in saving these buildings. You just have to respect history. It is a travesty to see these buildings- that were the cradle of communities and our civilisation- fall into disrepair or even get demolished
These Churches should not become financial assets- not yoga studios, not backdrops for light shows, not a rental opportunity. We should allow them to remain as sacred spaces- the preservation of our history is enough
When you take on these sorts of projects, people will say, "Oh, but these are money drains! They will just need continuous repair- and you'll have nobody to sell them to!" Consider perhaps that in this you will find the whole point
You could save a Church for low six figures. A very wealthy person could save a lot of them. I have taken on one, and it has been one of the most beautiful and meaningful projects of my life
Gemini 4 Argon on Google Cloud is built to help solve your business’s hardest problems.
@Amplitude_HQ explores how Gemini 4 Argon scored over 90% on their evaluations—building the charts that help Amplitude’s customers visualize the data they need to improve their products based on client’s feedback.
Watch the full interview here → goo.gle/3WVeA1T
A new change in Brave for iOS you may have missed:
When you're using Ask Brave or Leo, you can now long-press on embedded links or videos in the answers to preview them. 🔎
You can then tap this quickview window to see it in a full tab.
'Two Lily Bulbs.' (1952) Eliot Hodgkin was a meticulous painter of still life and as good at detail as the 18thC German botanist and artist Georg Ehret or Pierre-Joseph Redouté; it has botanical accuracy, aesthetic appeal and is painted with great affection for his subject.
ICYMI, we’re partnering with @Oracle to bring Google TPUs to Oracle Cloud Infrastructure in 2027.
OCI will be the first hyperscaler outside Google to offer TPUs, giving you more choices for purpose-built compute → goo.gle/3Wgxm3H
The famous Zenith cal 135. The competition version won the Neuchâtel trials every year from 1950 to 1954. The secret is the huge balance wheel (the gold wheel at lower left with the coiled spring in the middle).
Back in March, our team submitted a formal proposal for #Devcon9 to be hosted in Portugal's capital, Lisbon.
Since then we've been lobbying for this to happen around the clock.
Live from Mumbai, we're so happy to share the official announcement: Devcon 2027 will be in Lisbon!
Rovers, landers, aircraft, and astronauts 🚀
Day 1 of the first-ever MAX POWER aerospace expo and air show was unforgettable! Thanks to the thousands who joined us to celebrate American innovation and technology at @NASAKennedy.
Up next: Day 2. Stay tuned!
Asahi changing to GPLv2 changes nothing, btw. The Linux kernel is already GPLv2! We make all the source changes we have against the Linux kernel available, as we do with anything based on Asahi. Omarchy itself is MIT, the most permissible license. Enjoy!
Most enterprise data is dark data.
Smart Storage flips that by classifying unstructured data right where it lives so agents can reason over it.
Catch the full Google Cloud Live podcast for the deep dive → goo.gle/3V5AS0m
We had three AI models build cartoon characters in 3D and compared each one with a professional artist's model of the same character.
The best build scored 94/100 for shape similarity. It still got the face wrong. The artist's character looks serious. The AI's looks wide-eyed.
This week’s Paper Club is all about AI for biology.
Sequencing costs have collapsed, biology is generating more data than researchers can make sense of, and the models are beginning to catch up. The opportunity now is to move from reading biological data to modeling and designing living systems.
We brought together researchers and builders working across cancer genomics, virtual cells, genome language models, and biological design to show what that shift looks like in practice.
We start with a single patient, asking how AI can build a research program around their cancer, then zoom out to whole cells and genomes. Along the way, we look inside a language model trained on DNA and explore how in-context learning emerged even though the model was never explicitly trained to do it.
00:00 - Is the Turing test solved? A live experiment
03:22 - Why now is the best time for AI Bio
08:26 - Alfredo Gonzalez: cancer as a data problem
29:50 - Yusuf Roohani: virtual cells and autonomous research
51:47 - Garyk Brixi: what a model learns from DNA
1:09:57 - Divya Nori: few-shot prompting for biological design
@UKGInc is transforming work for tens of millions of employees across 80,000 organizations—using Gemini to move HR systems of record into systems of action ↓
Nearly 13 Billion token in 7 days.
Yes @OmarchyMac Is coming for the M4 Mac Mini.
In the last 24h: Aurora Linux on the M4 mini with the HDMI desktop, GPU compute and the front USB ports working (my keyboard and mouse right now).
Hear how @Rakuten explores how Gemini 4 fared on their private benchmark testing and how the company is using models to power overnight tasks → goo.gle/4j42EDB
youtube.com/watch?v=8Ttqph…
First comment:
"Perfect movie
Perfect music
Perfect actors
Lov & gratitude Hitch 📷"
Saw this at the Stanford Theatre recently, old-time prices, the Mighty Wurlitzer playing beforehand. Someone shouted out kudos to Eva Marie Saint (101), still with us.
The @huggingface crew is here in Doha till 7th for a grand Hackathon in collaboration with QAI.
We're excited to be in this part of the globe and build something cool!
 Andrej Karpathy@karpathy